

monitor extension traces a standalone tool call as one span.
Query metrics
Query aggregate metrics over a time range.--from and --to take an ISO instant or a relative token (7d, 30d); --granularity is hour, day, or week.
List and read traces
List runs
--export.Read one trace
--export.--user, --session,
and --version filter to one person, one conversation thread, or one preset
version.
Reading traces
A trace is a tree of spans. Every span carries a neutral kind the monitoring backend maps its own observation types onto:inputTokens, outputTokens and totalTokens,
each null when the producer reported none. A model call’s input and output are
recorded in the OpenTelemetry GenAI message shape — a list of {role, parts}
messages, each part a text, a tool_call, a tool_call_response or another typed
part, and an output message’s finish_reason — and the Studio renders each part by
its type. A value that is not in that shape shows as a JSON tree, so every value
stays visible.
An empty input — absent, null, a blank string, [] or {} — is left out of the span
detail. An empty output of a span that ended without error keeps its label (Result
or Output) over a plain note: “The tool returned an empty result.” for a tool call,
“The span recorded an empty output.” for any other span. A span still running, or one
that failed, shows no such note; a failed span shows its error.
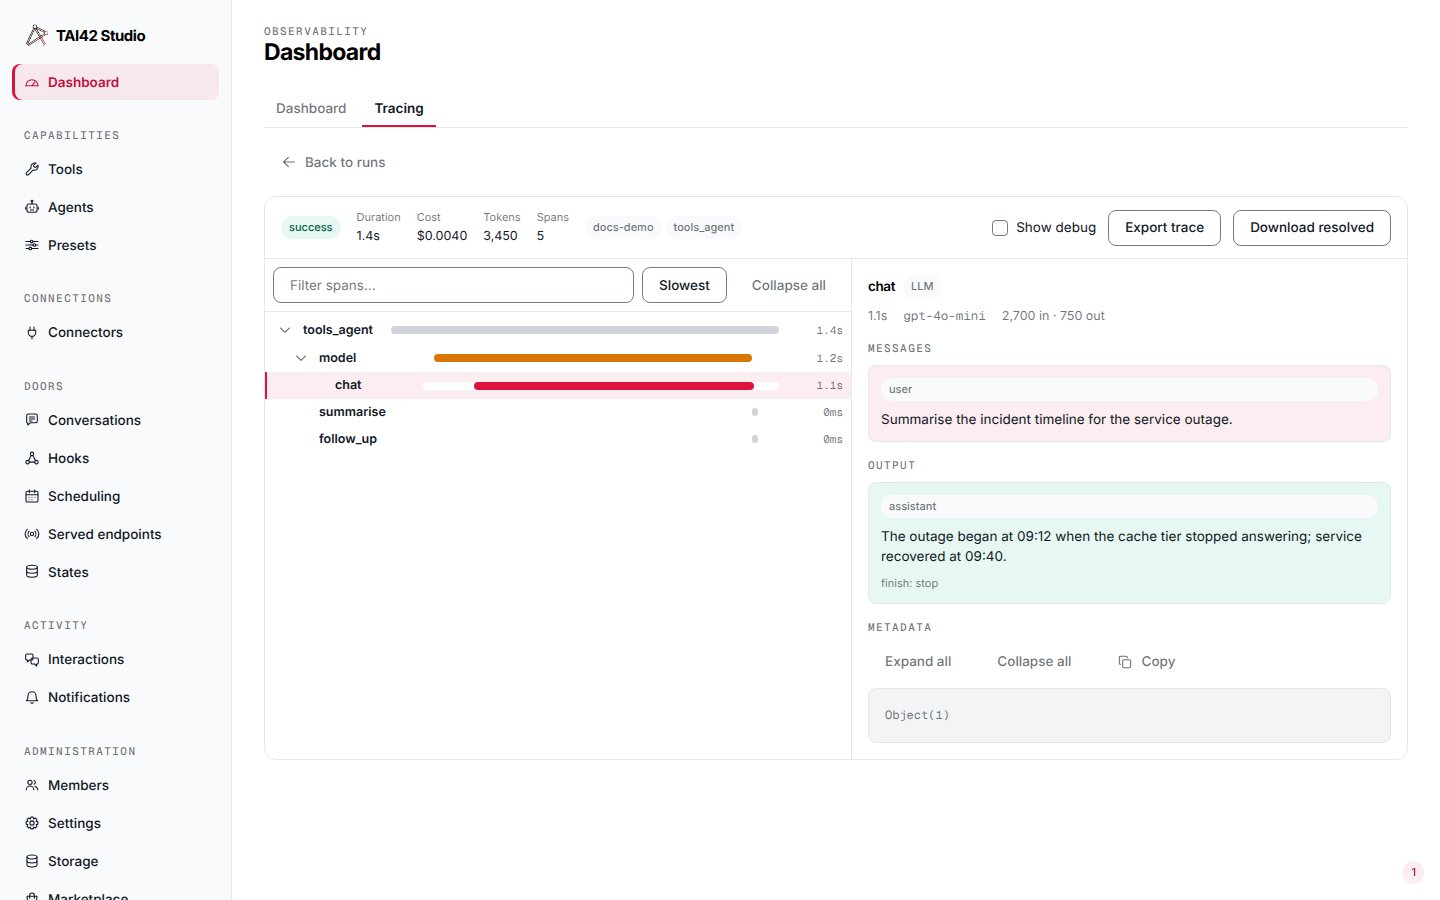
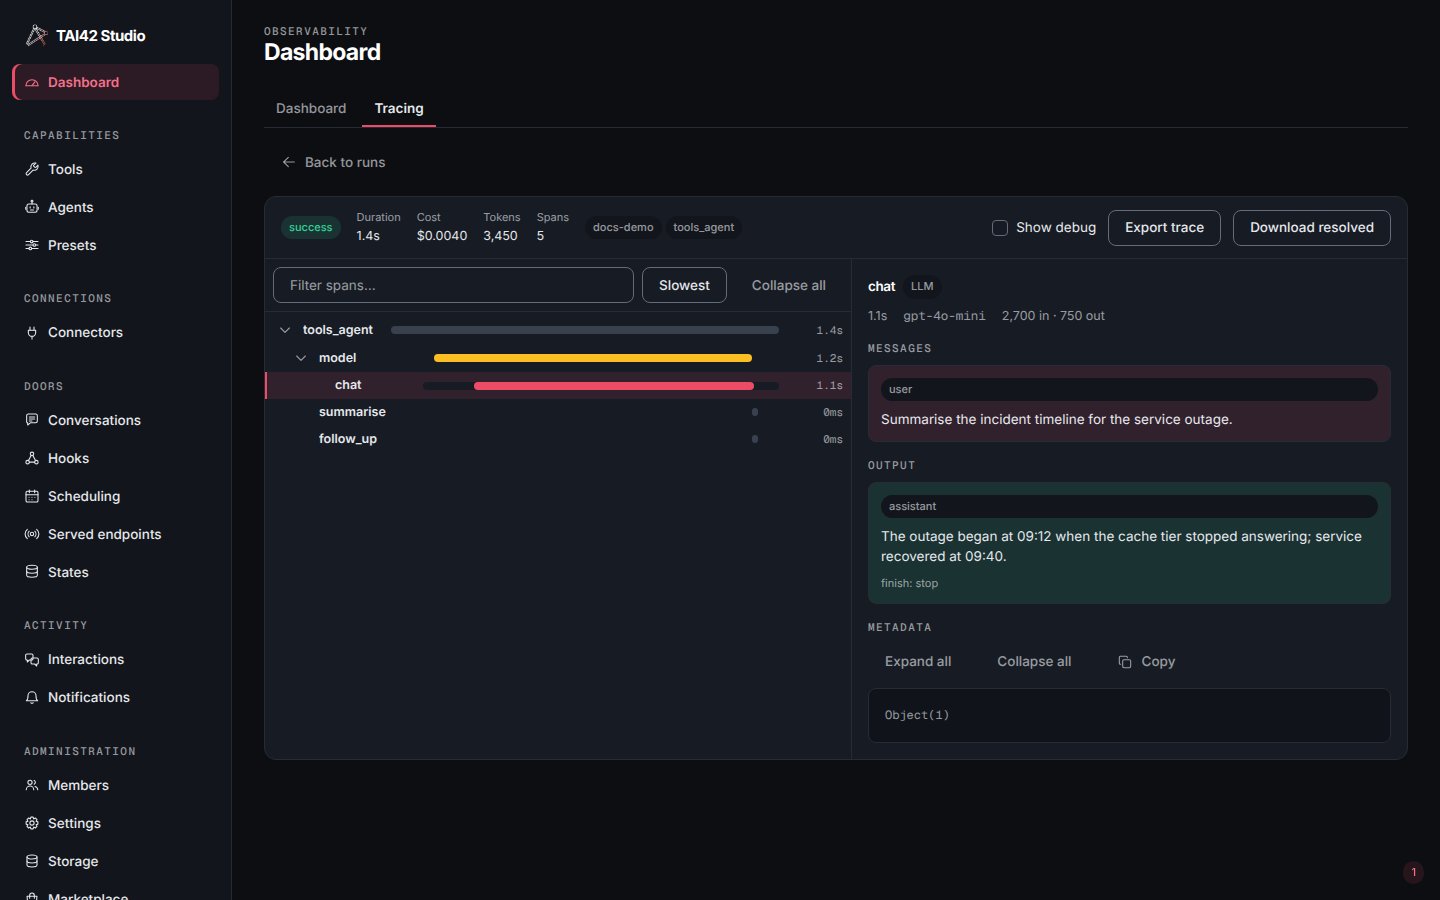
A model call's span detail: the input and output messages rendered part by part, the output with its finish reason.
{"$tai42_unrecorded": true} was produced while monitoring
was off; the Studio notes it under the tree.
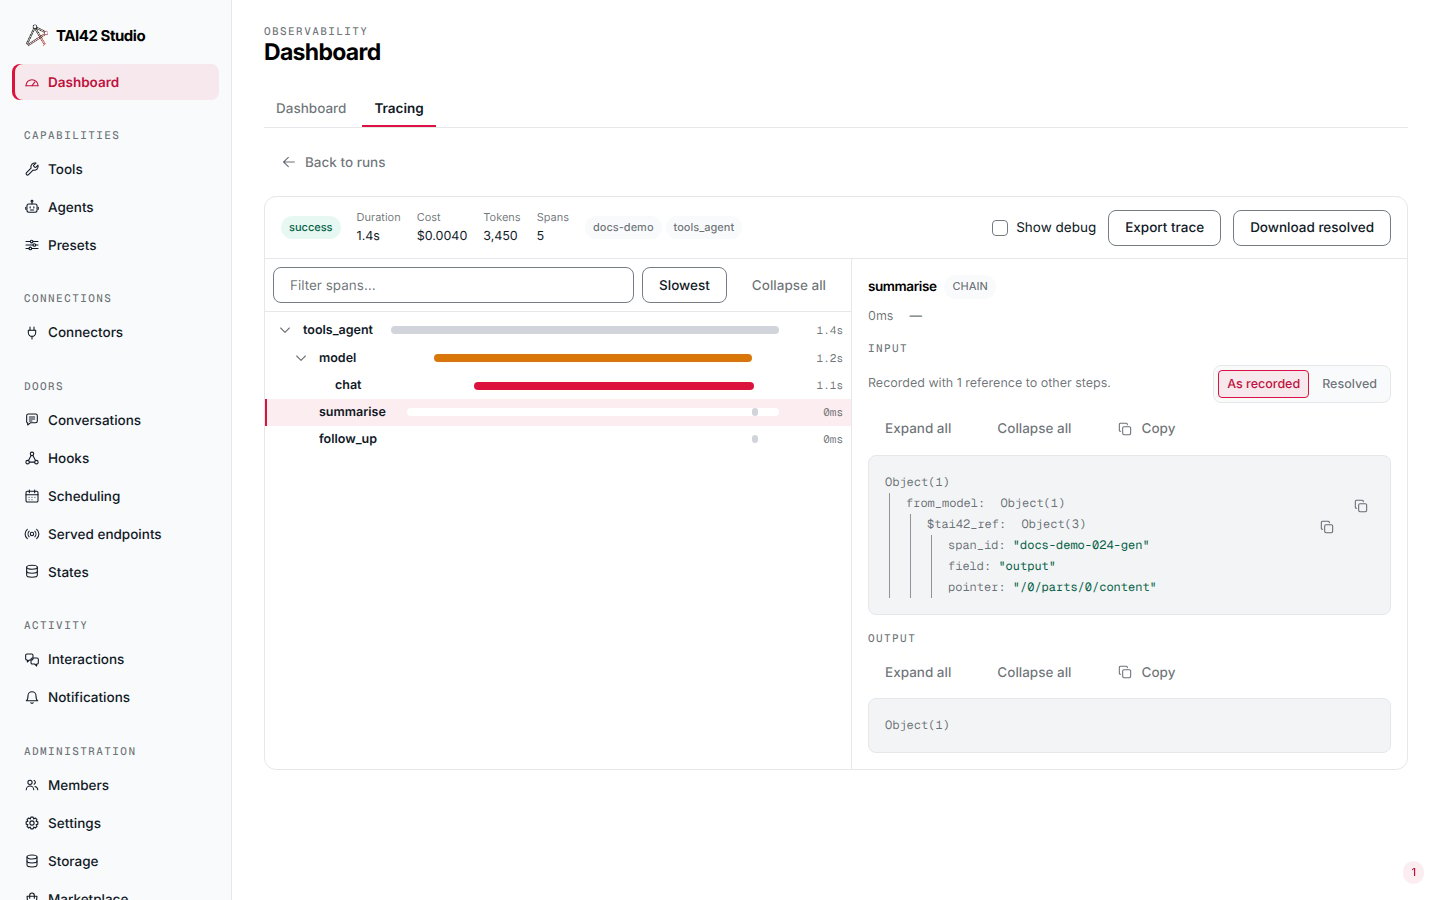
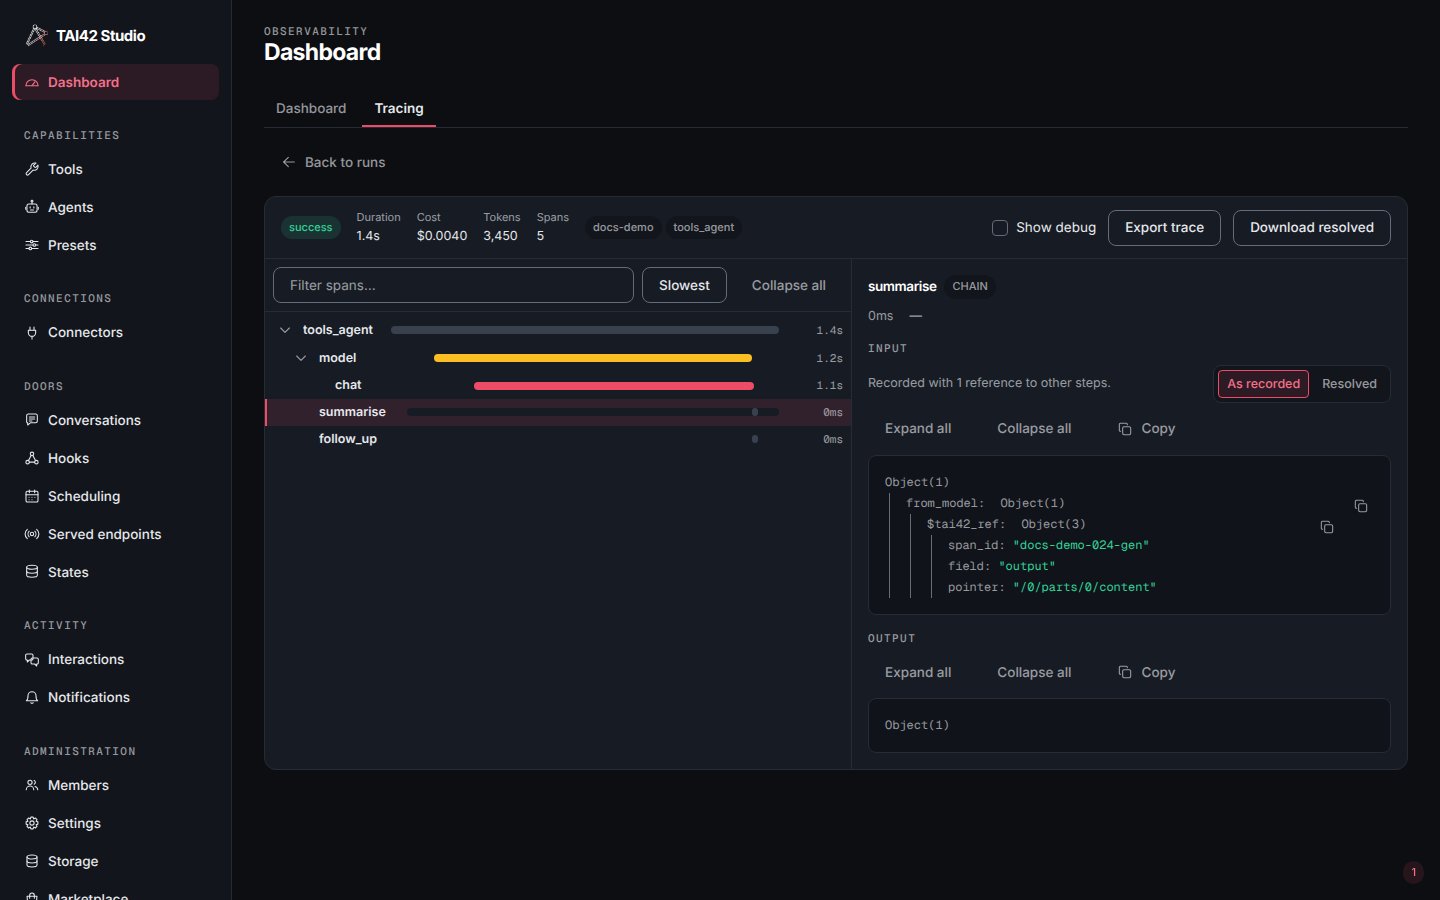
A step's input as recorded: one reference to another step's output, shown with its span id and pointer.
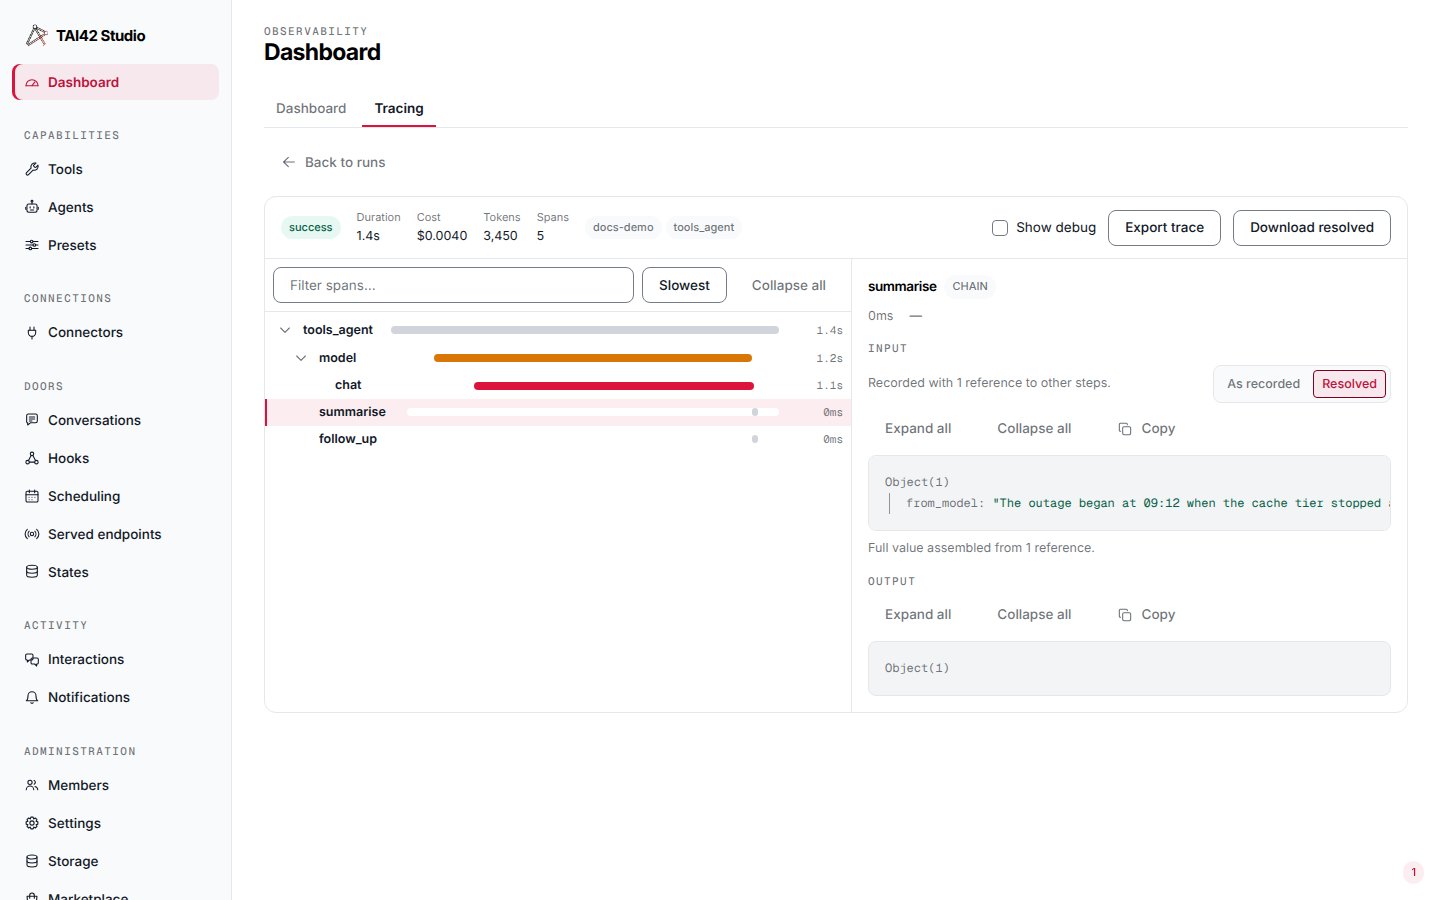
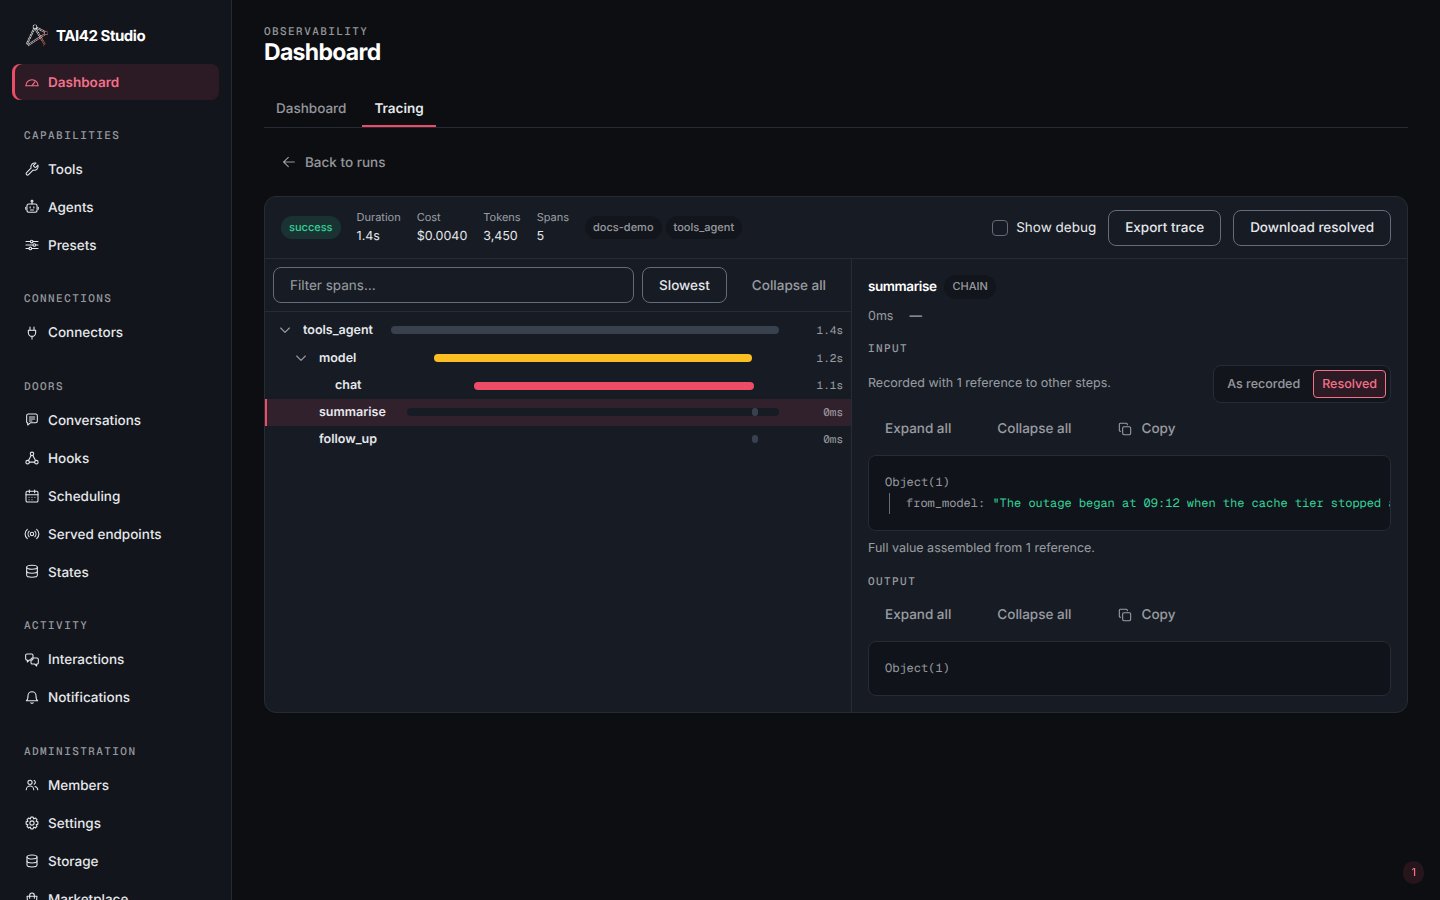
The same input resolved: the server assembles the full value from the referenced record.
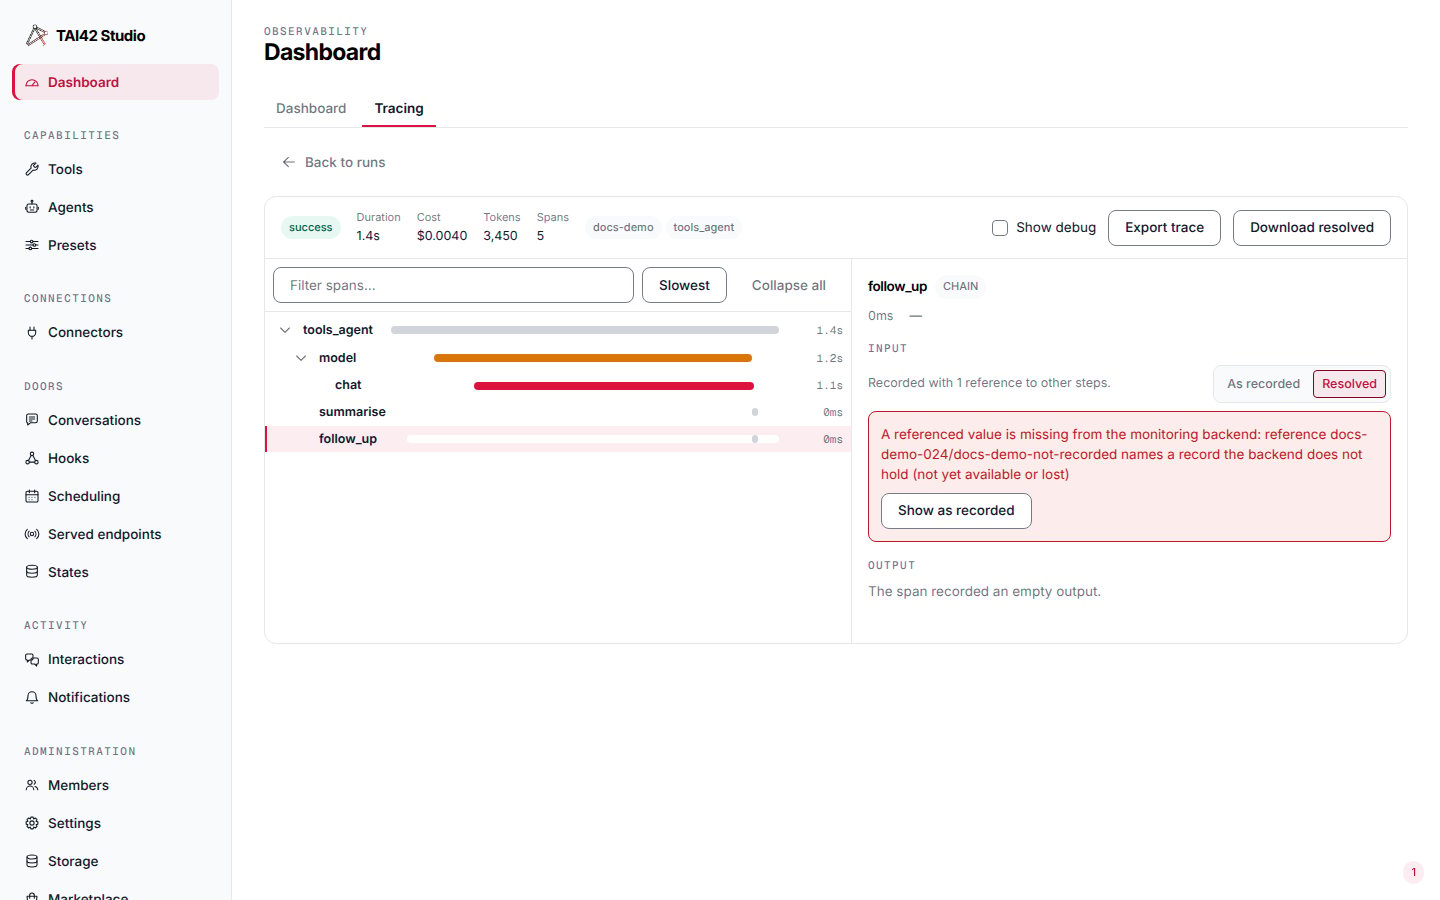
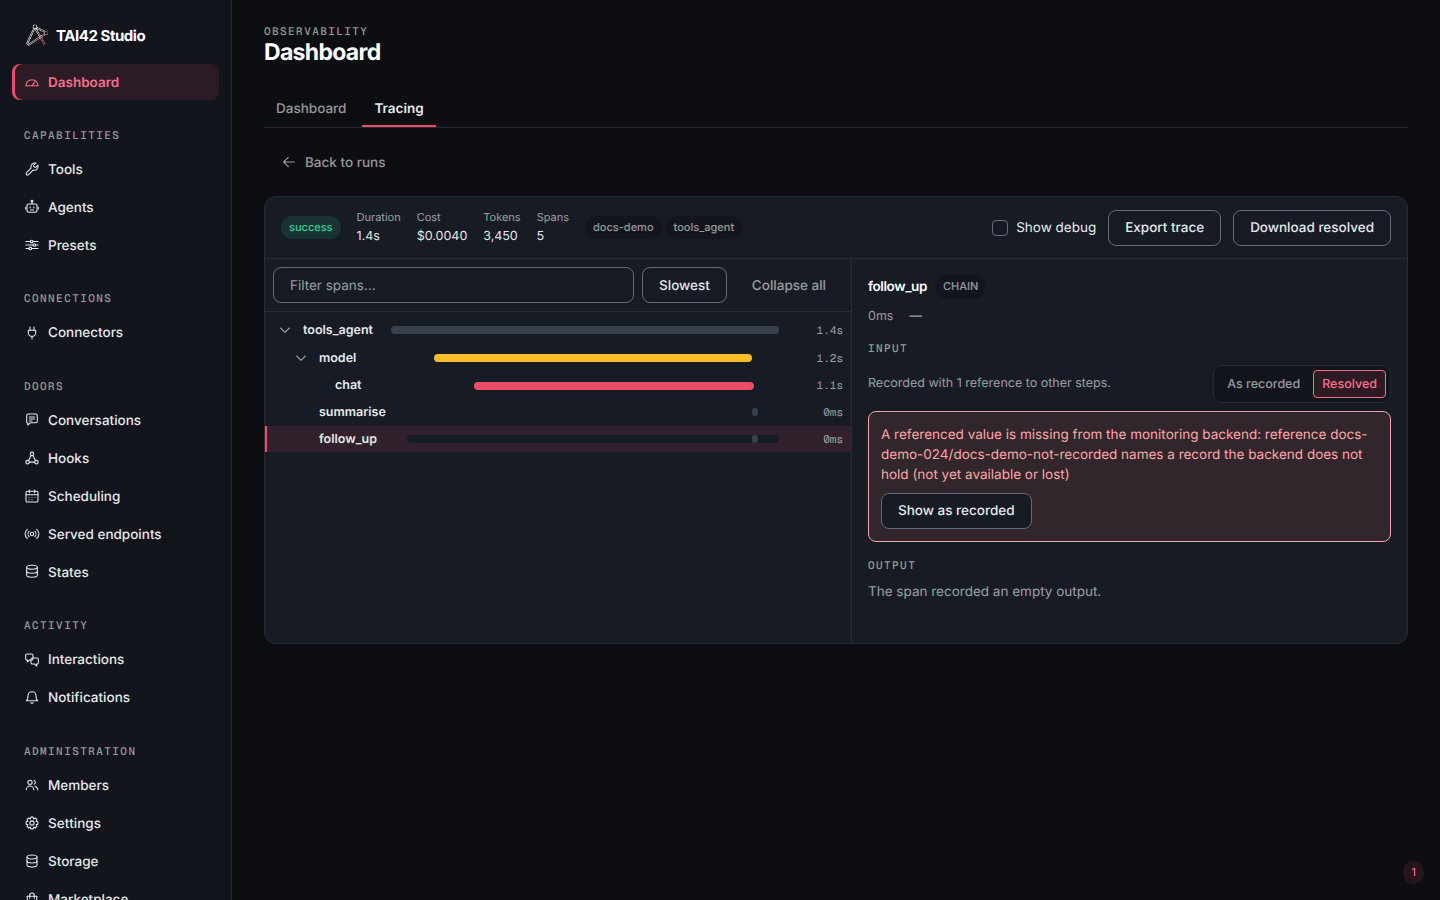
A reference to a record the backend does not hold: the Resolved view says so and offers the recorded view back.
parentId before opening a value:
What the backend serves
Each monitoring backend declares the largest run-list page it serves, the run-list sorts it serves, and the filters each sort cannot be combined with. The run list capspageSize to that page maximum (never refusing a larger one), and the export
is one backend read of up to 5,000 runs. The Studio waits for the declaration before
it reads runs, offers only the served sorts, disables a filter the active sort cannot
carry, and never sends a combination the declaration excludes. A link with a sort the
backend does not serve, or with a sort and a filter it does not combine, is shown as
it is, with a notice saying why and a Sort newest first button; the link is not
changed until you press it.
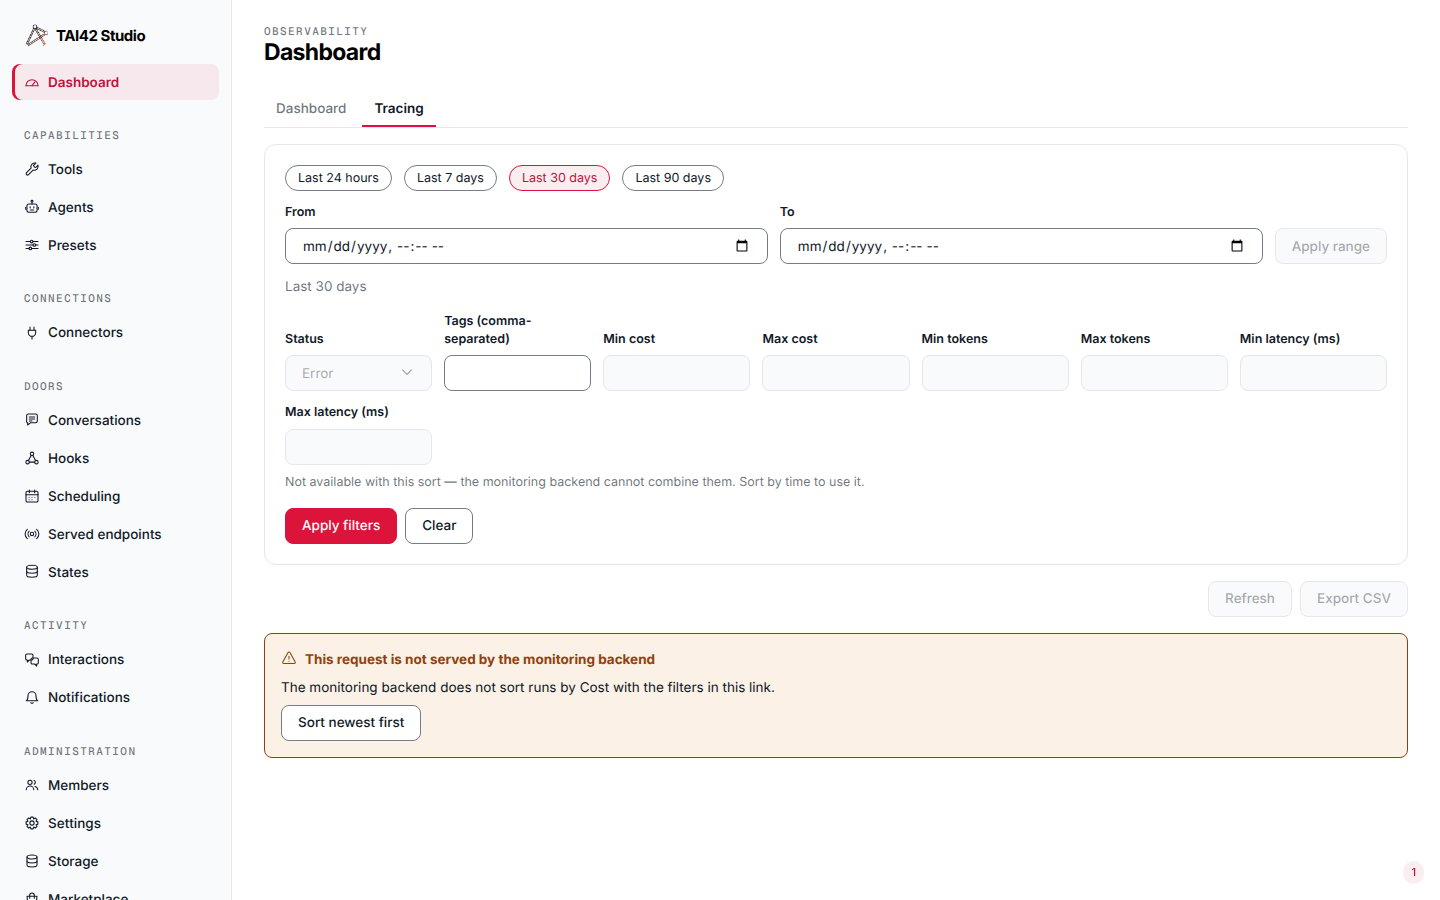
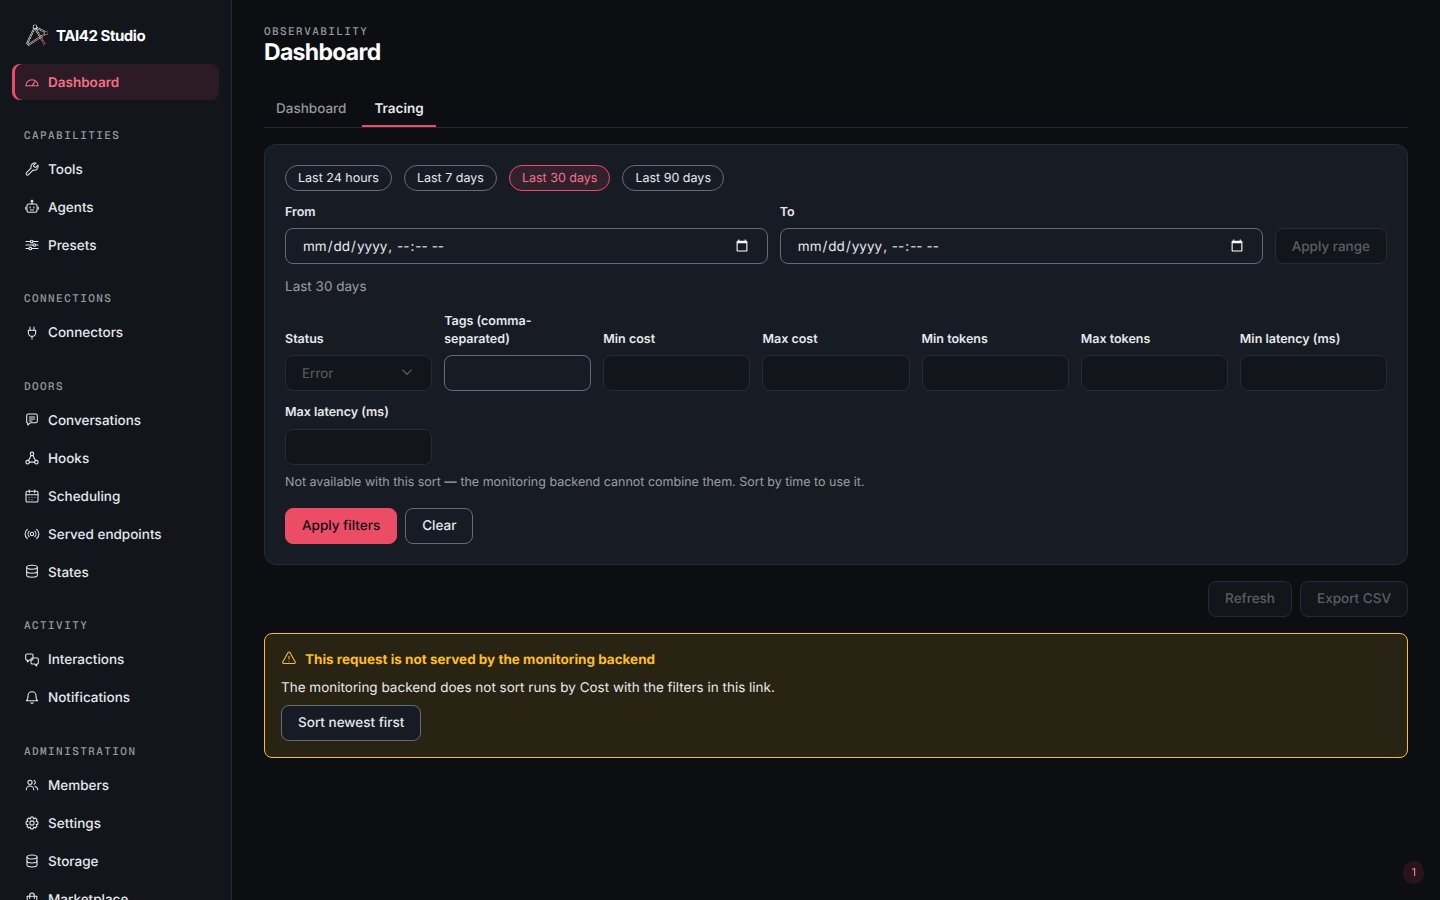
A link that sorts by cost with a status filter, opened on a backend that does not combine the two: the link is shown as it is, with a notice saying why and a Sort newest first button.
GET /api/observability/capabilities; the example is shortened.) A sort the
backend does not list, or a combination it declares excluded, is refused with 400
and the code monitoring-read-not-served; the filters stay. A read the backend
serves within a bound answers 400 monitoring-read-too-broad past it, with how to
narrow it.
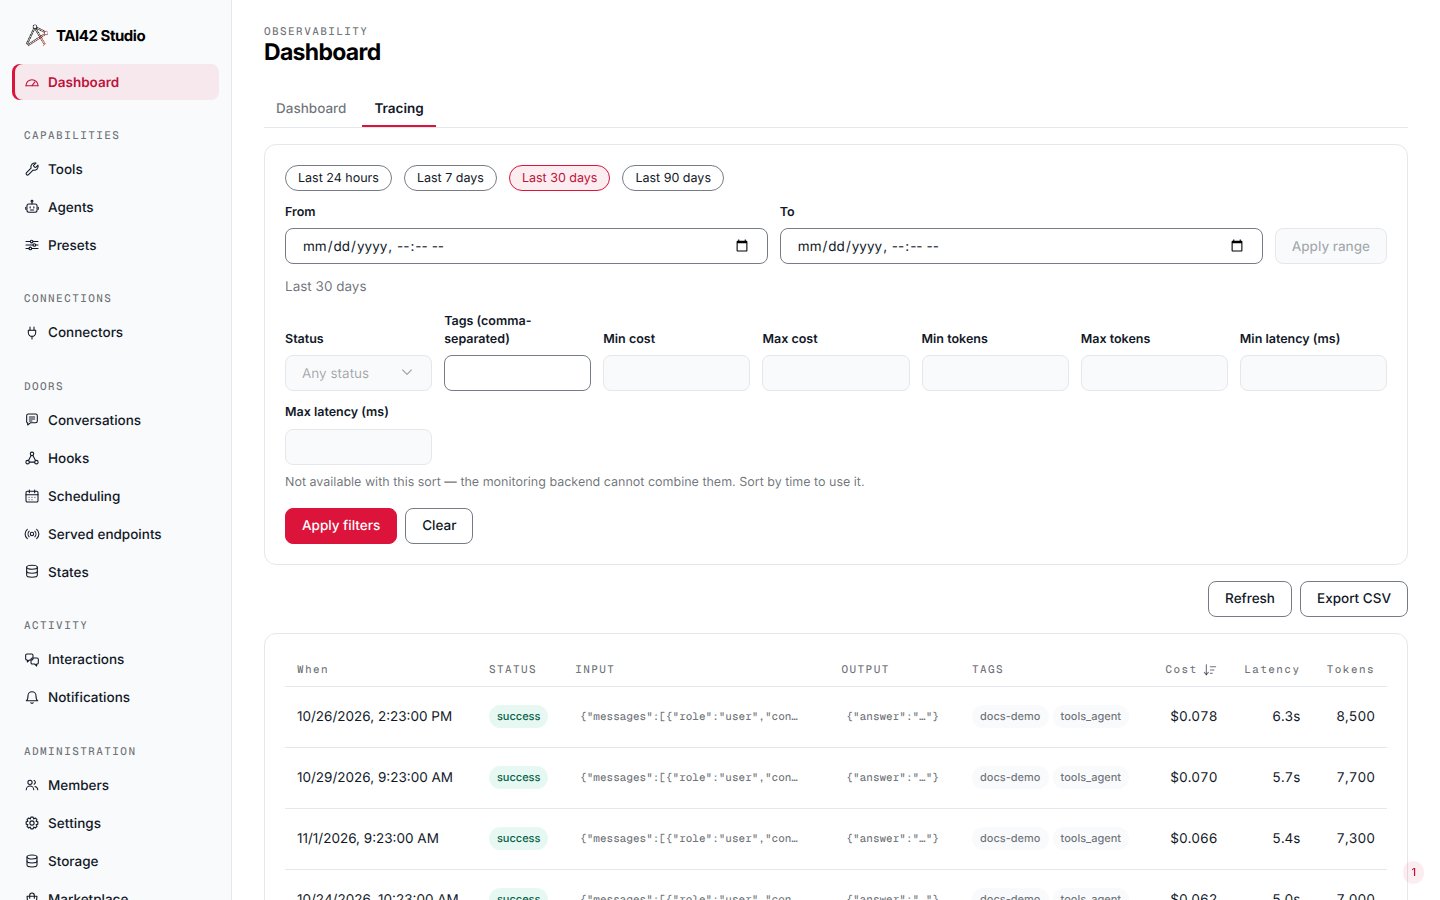
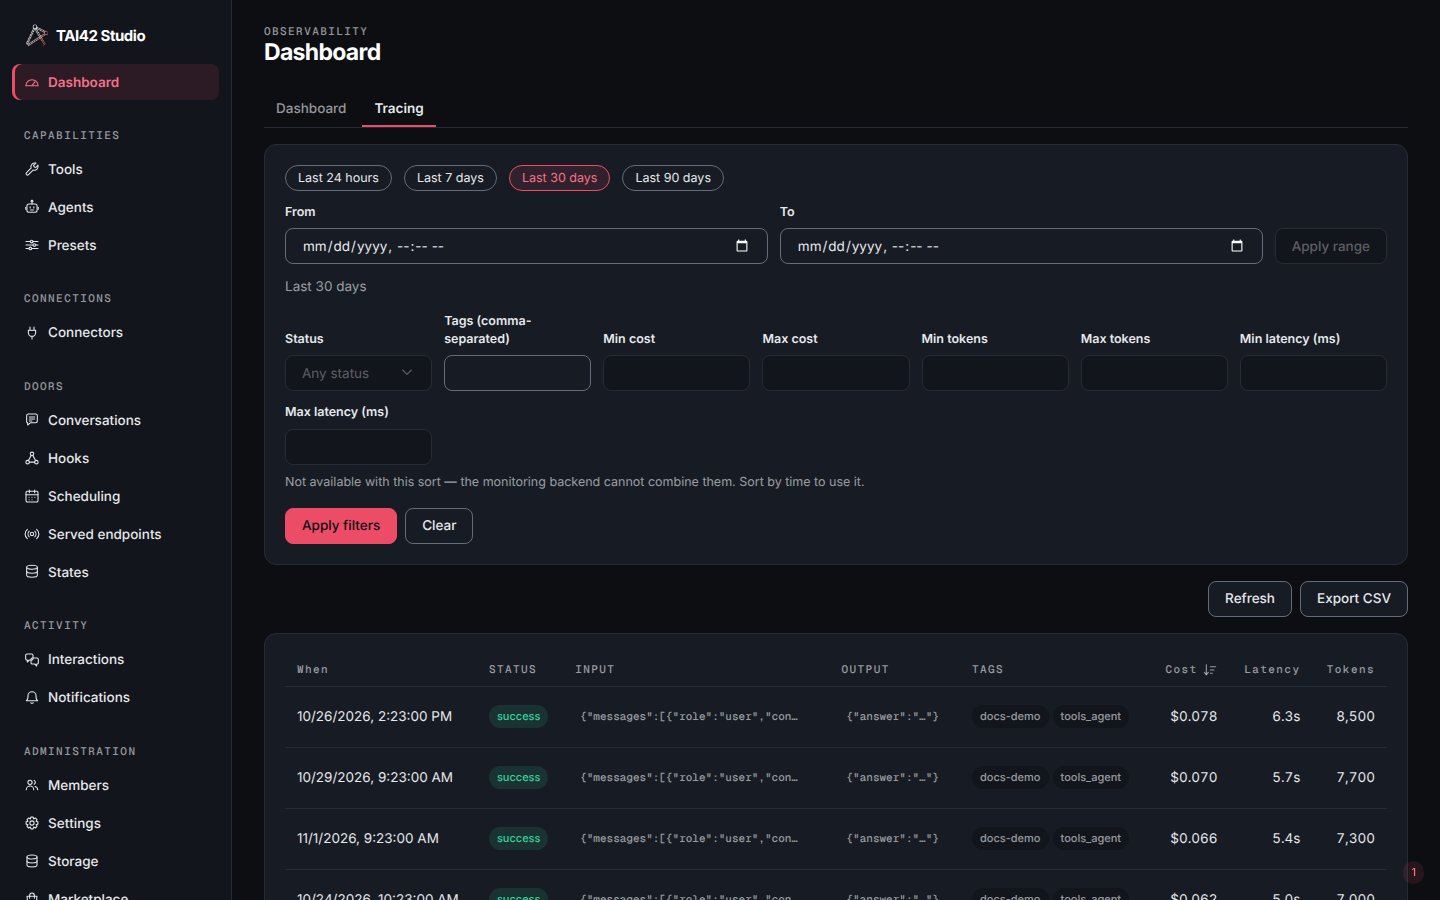
The Tracing tab sorted by cost, under a backend that declares the filters a cost sort cannot carry: those filters are disabled while the sort is active.
List runs without the vendor
The platform keeps its own runs index: one row per registered-preset run, persisted in the platform’s own Postgres — so a deployment enumerates its runs without reaching for the monitoring backend at all. Each row carries the run id, the preset name and version, the run’s attribution user and session, its outcome, its start/end window, and the monitoringtraceId as a deep link into the full trace.
--preset, --version, --user, --session, --interaction,
--outcome, and a --from/--to start-time range; the same filters ride
GET /api/runs as query params. Outcomes are running, success, error,
parked, and aborted — a cancelled run records aborted, never error, and a
crash-interrupted run stays honestly running with no end time.
A run that parks on an async question and resumes later is two dispatches — two
rows. The shared interactionId joins them: the parked row records the
interaction it parked on, the resume’s row records the same id, and
--interaction <id> returns that park’s lifecycle pair.
A run that resumes or takes parked interactions itself — a door or tool
resolving caller asks — records each id it acted on in
its resumedInteractions list, across its whole dispatch span, nested inline resumes
included (an inline resume opens no row of its own). The list is empty when the run
resumed nothing.
Rows are kept forever by default. Set TAI_RUNS_INDEX_RETENTION_DAYS and call
the prune on a cadence to bound the table:
One run, one trace
A run that dispatches nested work keeps a single trace. A nested run invoked as a tool and an agent driven by another run join the dispatching run’s trace — their spans nest inside it rather than minting a fresh, orphaned trace — so one participant interaction reads end to end as one trace. A run that parks on an async question and resumes later — days later, on another worker — rejoins its original trace. One feature run is one trace, however many sub-runs it fans into internally. An agent that drafts then critiques then finalises, or one that polls several voters before a judge, nests every sub-run inside the feature’s one trace rather than opening a separate root per sub-run — so the whole feature run reads as a single tree, with the sub-runs as nested spans. A run dispatched directly — through the sync run-tool API, a background or scheduled tool run, or the MCPtools/call edge — opens its own trace root when
no trace is already open, and nests under the existing root otherwise. That
decision is made once at the shared run chokepoint where the run record is
registered, agnostic to what the preset wraps. Every runs-index row therefore
carries a traceId deep link whenever a monitoring backend is active; with the
no-op default there is no trace to link.
Every feature’s model calls
Every platform feature’s model calls are traced. The monitoring callback is attached once at a shared seam that every agent kind passes through, so a model-usage span lands on the run’s trace whatever the kind — an agent driven by another run, a multi-phase agent, or a voter-and-judge agent — and a new agent kind inherits the coverage without wiring of its own. An agent that runs its model calls inside its own sandbox session bypasses that seam and is covered a different way, emitting its own usage (see the sandbox note under Attribute a run below). Model calls made inside a tool are not a feature: trace those with themonitor
extension instead.
The classifier is a feature’s model call too, but it is its own model kind,
not a chat model, so it carries no chat-model callback. Each classifier call
still records a model-usage span on the run’s trace — its model id, token usage,
provider request id, and the call’s latency — resolved onto the run’s trace by
the same lineage rule, or onto a fresh root for a standalone call. Embeddings
are not recorded as model calls.
Send outcomes and delivery receipts
Every outbound channel send made inside a run’s trace — a run’snotify_user
send, a question delivered to a person, an inbound participant notice — records a
send:{channel} span around the provider call. The span carries the recipient
as its input, and the notify_user seam adds the provider’s message ids as its
output; a raised error marks it ERROR with the failure detail: error.type,
error.kind (unknown for an unclassified exception), retryable, and a
positive retry_after the medium asked for, stamped only alongside
retryable: true. A seam that retries emits one span per attempt, stamped with
retry.attempt, and there retryable is the seam’s own decision: true
exactly when another attempt follows, false on the last one (the attempt
budget is spent, or too little of the ask’s window is left for the backoff). So
“attempt 1 failed retryable, attempt 2 accepted” is visible rather than
collapsed. On a single send, retryable is the error’s own classification
(false for an input error). A tool dispatched under a retry policy records the
same keys on each tool-attempt:{tool} span. These keys are ordinary span
metadata.
Acceptance is not delivery. On channels with a delivery-status webhook (WhatsApp,
Twilio), the provider’s later status closes the loop: the status is resolved back
to the originating send and posted as a delivery_receipt event on that run’s
trace, nested under its send span — a failed delivery as an ERROR event
carrying the provider’s error detail. The receipt is observability only: it
annotates the trace, never re-sends, and never fails the run.
A send on a channel with a bridge route is also a send
record in its conversation thread. When
nobody can tell whether such a send reached the participant — it passed its bound, it was
cancelled mid-call, an ask attempt timed out, or the process stopped after the record was
written — the record ends outcome_unknown, keeps the reason in its error, and is never
re-sent. Each such end logs a WARNING that names the record:
- a send that passed its bound or was cancelled mid-call:
conversations: send record <id> on <channel> to <address>: <error>; not re-sent, where<error>is the record’serrorand ends “the outcome is unknown”; - a send record a stopped process left
sending, settled by the sweep or the boot redrive:conversations: send record <id> on <channel> to <address> was sent, outcome unknown: the process stopped before the medium answered; not re-sent; - an ask whose attempts timed out:
conversations: send record <id> on <channel> to <address> for interaction <interaction id>: delivery attempts [<numbers>] timed out unanswered; the participant may have received the question, where the attempt numbers print as a list, for exampledelivery attempts [1, 2] timed out.
?status=outcome_unknown filter (tai conversations threads <route> --status outcome_unknown) finds a thread only while its newest record is
outcome_unknown; once a later record lands in the thread, the filter no longer finds it.
The failed listing (tai conversations failed) holds failed records only. To find every
outcome_unknown send, search the logs for the WARNINGs above (each names the record id);
to read one, open its thread’s transcript (tai conversations transcript <route> <thread>), where each record shows its delivery_status, or the record itself (tai conversations get-message <route> <id>), whose admin view holds its error.
failed from a reachable-channel
refusal of a turn’s reply also sends the participant a best-effort could-not-deliver
notice — its own failure logged at ERROR and never retried — while a
transport-exhaustion failed, or a refusal of an operator’s hand-injected send, sends
none; the failed-delivery listing and the trace event remain the signal either way.Trace a standalone tool call
A tool call made outside any run has no trace of its own. Load themonitor extension and stack it onto a tool to record the call as one live span. Load the module, then attach monitor to a tool.
monitoring_module. Without one, the runtime uses a no-op default and there is nothing to query.Attribute a run and roll up cost
Every run’s trace can be tagged at the shared run chokepoint with the run’s own identity — the run kwargs the operator defines per delivery, carried verbatim as aRunAttribution of tags and metadata, wired once at the shared seam so every
door attributes. The attribution is set on the trace from its first span, so it
covers the whole run — the user, session, tags, and version are on the trace
before the first model or tool span opens, not attached to the later spans
alone. That lets you group cost and tokens by identity when you
query traces: per-delivery attribution, with no tenant system and no
per-tenant isolation — attribution only. Metrics aggregate over a time range
alone — tai obs metrics takes no identity filter, so slice by identity on the
trace list and roll the cost up from there.
There is no cost-aggregation module. Cost aggregation is a tool or a view built
over these attributed traces: the platform ships the generic attribution enabler,
and assembling spend into a cost view is delivery work on top of the trace data.
The identity dimensions
Beyond the per-delivery tags, the runtime stamps every conversation-driven run with generic identity at the same shared seam, and the monitoring backend maps them to its native trace dimensions:user_id— person-id-first: a run with a resolved person is attributed by that person’s stableperson_id, so one human’s runs group together across channels. With no person it falls back to the raw{channel}:{address}the door saw, or the bare address on the API door.session_id— the resolved conversation thread, so a whole back-and-forth reads as one session.tags— the conversation route asroute:{name}; a registered preset dispatch addspreset:{name}andpreset-v:{version}and lifts the version onto the trace’s native version dimension. Only the outermost preset stamps: a nested sub-preset never pollutes the root identity, and a draft run carries no preset stamp at all.
GET /api/observability/runs
takes user, session, and version params, plus any number of
meta.<key>=<value> params — each one a string-equality clause on the trace’s
metadata.
claude_code
adapter emits the SDK-reported usage and cost into the active trace itself — so an
attributed claude_code run’s spend rolls up with everything else. Run standalone
with no ambient trace, its model-usage span is the root of its own trace, so a standalone sandbox run is observable on its own rather than
emitting nothing. The boundary:
the toolbox prometheus_metrics extension records latency and count only; it is
not the cost seam.The monitoring pipeline
Every monitoring backend records through one OpenTelemetry writer: each serve and backend process exports OTLP over HTTP to an OpenTelemetry collector running as its own container. The process encodes each recorded value once on the caller’s thread and hands spans to the SDK’s batch processor; the protobuf encoding and the network send run on the processor’s worker thread, and the collector does the batching, retrying, mapping to the backend’s vocabulary, and the send. A deployment changes backend by changing the collector’s exporter and transform; the monitoring-langfuse page carries the Langfuse mapping.Writer settings
The writer reads the OpenTelemetry SDK’s own standard environment — no platform-specific names.OTEL_ATTRIBUTE_VALUE_LENGTH_LIMIT,
OTEL_SPAN_ATTRIBUTE_VALUE_LENGTH_LIMIT) have no effect: a recorded value is never
truncated.
Each value recorded once
A model call records its input and output messages in full, in the OpenTelemetry GenAI message shape, plus the generated message’s full record; a tool call records its arguments and result in full. A chain record (a graph node, its root) never copies the run’s data: a value already recorded appears as a reference to the record that first holds it, the one-key object{"$tai42_ref": {"span_id", "field", "pointer"}} (with a trace_id when the record
is in another trace). {"$tai42_unrecorded": true} marks a value that exists but was
produced while nothing recorded. A reference resolves through the reader:
pointer is an RFC 6901 JSON pointer, empty
for the whole value) with every reference on the way and inside it resolved; the
second exports the whole trace resolved. The export’s resolve is a boolean, false
when absent. true, t, yes, y, on and 1 read as true, and false, f, no,
n, off and 0 as false, each word in any case; any other value, the empty one and
one with surrounding spaces included, answers 400 with the field and the error type,
{"error": [{"loc": ["resolve"], "type": "bool_parsing"}]}. A reference the backend does not yet hold
(its ingestion is asynchronous) or has lost answers 502 with the reason “not yet
available or lost” — retry once ingestion catches up. Every SecretValue in a
recorded value is written as [secret].
Dropped and failed records are counted and alerted
Nothing the writer cannot deliver is silent. Every process counts it, and/metrics
serves the run family’s totals:
monitoring_export_failed platform event
within 15 seconds, whichever process of the family notices it first. Its payload is
the growth since the last alert:
8888). Alert on:
otelcol_exporter_queue_sizeagainstotelcol_exporter_queue_capacity— the batches waiting to reach the backend. The collector retries a send it cannot make until it is delivered, so a backend that is down or unreachable (or an unsetLANGFUSE_HOST) fails no span: the collector stays ready, logs each retry atINFO, and only this queue grows. A queue that keeps growing is the signal.otelcol_exporter_enqueue_failed_spans— spans refused because the queue is full.otelcol_exporter_send_failed_spans— spans the backend refused for good, logged atERRORand dropped (for example, a missing or wrongOTEL_COLLECTOR_LANGFUSE_AUTHanswered401).otelcol_receiver_refused_spansandotelcol_processor_refused_spans— spans the collector refused on intake (for example, over its memory limit).
Write a monitoring backend
A backend plugin implements a reader for its backend and registers the shared writer with it:MonitoringReader. Beside the reads, it declares what it
serves and maps its own vocabulary onto the neutral one:
get_observation(trace_id, observation_id)returns one observation with its full input and output — the call references resolve through.list_capability()returns aListCapability: theOrderBy.fieldvalueslist_tracesserves, and for each sort theMonitoringFilterfield names it cannot combine with.list_tracesraisesMonitoringReadNotServedErrorfor a sort or a combination outside it; the same error answers a measure or dimension outsidemetrics_capability().MonitoringReadNotSupportedErroris only for a backend that cannot read at all.export_traces(from_timestamp=…, to_timestamp=…, max_rows=…, filter_=…, order_by=…)returns, in one read, the run summarieslist_traceswould page through, in its order: at mostmax_rows + 1rows, so more thanmax_rowsmeans more runs match. It takes the same window, filter and sort aslist_tracesand raises the same errors; a bound the backend cannot read past raisesMonitoringReadTooBroadError. The run export reads through it.max_page_size()returns the largestlimitonelist_tracescall accepts; a largerlimitraisesValueError.- Each
MonitoringObservationcarries akind(LLM,TOOL,CHAINorEVENT) mapped from the backend’s own observation type, and theinput_tokens,output_tokensandtotal_tokensthe producer reported. - Each
MonitoringTraceSummarycarries the trace’s owninputandoutput; the platform bounds them for the run list. list_spans_in_windowselects steps by the producers’ marker, never by span names: a record whose metadatatai42.step_roleisgroupingorsub_stepis never an item, and neither is a model call nor an event.
Pending state saves
The state store’s pending saves publish Prometheus metrics on the server’s/metrics (the multiprocess-aware registry). Counters:
tai42_state_outbox_enqueued_total, tai42_state_outbox_applied_total{phase},
tai42_state_outbox_attempt_failures_total{phase,kind}, tai42_state_outbox_failed_total{phase},
tai42_state_outbox_divergences_total (an apply whose answer differed from the run’s
projection), tai42_state_outbox_discarded_total, tai42_state_outbox_retried_total,
tai42_state_outbox_lock_waits_total, tai42_state_outbox_notify_failures_total,
tai42_state_outbox_sweep_errors_total, and tai42_state_outbox_drain_waits_total{door}
(door is read or run_entry). Histograms: tai42_state_outbox_drain_wait_seconds{door} and
tai42_state_outbox_apply_latency_seconds (enqueue to records applied). Gauges, set by each
sweep pass: tai42_state_outbox_rows{status} and tai42_state_outbox_oldest_age_seconds.
Set alert rules on three of them: any increase of tai42_state_outbox_failed_total (a save
failed and holds its subjects), tai42_state_outbox_rows{status="failed"} above zero (a held
save still waits for an operator), and tai42_state_outbox_oldest_age_seconds above a few sweep
intervals (saves are not being applied). The failed save itself is listed under
tai states pending-saves list --status failed.
See also
- Live operations — status, retry, and runtime state.
- The MCP-citizen surface — progress and structured output that traces capture.
- CLI reference — the full
tai obs,tai traces, andtai runssurface.